Skip to content

Feed Forward Networks (FFN)

About

The d9d.module.block.ffn package implements the dense feed-forward networks of Transformer blocks.

SwiGLU

SwiGLU implements the SwiGLU layer: down(SiLU(gate(x)) * up(x)).

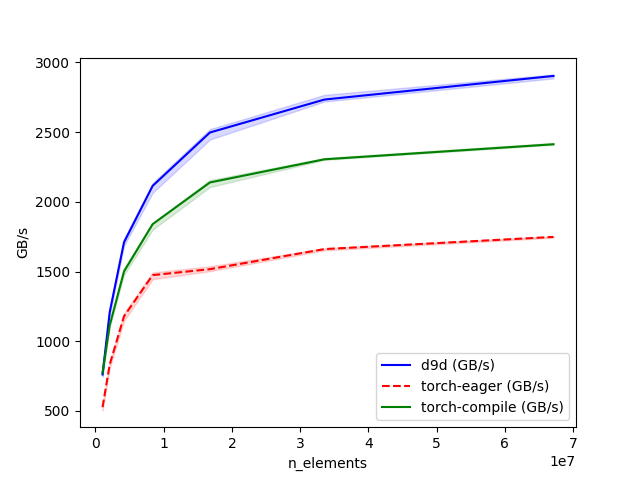
It computes SiLU(gate(x)) * up(x) with a fused Triton kernel, so it requires a GPU supported by Triton.

Kernel Benchmarks (bf16, H100)
Usage

1
2
3
4
5
6
7
8
import torch

from d9d.module.block.ffn import SwiGLU

ffn = SwiGLU(hidden_size=2048, intermediate_size=6144).cuda()

hidden_states = torch.randn(2, 16, 2048, device="cuda")
output = ffn(hidden_states)  # (2, 16, 2048)

API Reference

d9d.module.block.ffn

Feed-forward network layers.

SwiGLU

Bases: Module, ModuleLateInit

SwiGLU feed-forward network (FFN).

Computes down(SiLU(gate(x)) * up(x)). This is the standard MLP block of architectures like LLaMA.

__init__(hidden_size, intermediate_size, bias=False)

Constructs the SwiGLU object.

Parameters:

Name Type Description Default
hidden_size int

Hidden size.

required
intermediate_size int

Intermediate size of the FFN.

required
bias bool

Whether to use bias in the linear projections.

False
forward(x)

Applies the SwiGLU FFN to the input.

Parameters:

Name Type Description Default
x Tensor

Input tensor. Shape: (batch, seq_len, hidden_size).

required

Returns:

Type Description
Tensor

Output tensor. Shape: (batch, seq_len, hidden_size).

reset_parameters()

Resets module parameters.